
tokenlab
The same sentence, in Greek and in English. One of them costs 1.92x as much.

OPEN SOURCE
The same rule as the systems I build, in the open: every number on these pages is produced by code in the repository, and the repository is public.
The same sentence, in Greek and in English. One of them costs 1.92x as much.
I trained this model. Watch it think.
A 1,024 token chunk holds four times as much English as Greek.
An AI coding agent wrote down six failures 32 times in 108 entries, and kept making them.
This evaluation can tell 178 rows apart. It was asked about 5.3.
The same server, six seconds: 32.5ms at p95, or 337ms.
A cost heatmap over a prompt is flat at the grain everyone draws it at. The bill is how often you send it.
Where you cut a document does not decide whether you find the answer. It decides whether you are handed all of it.
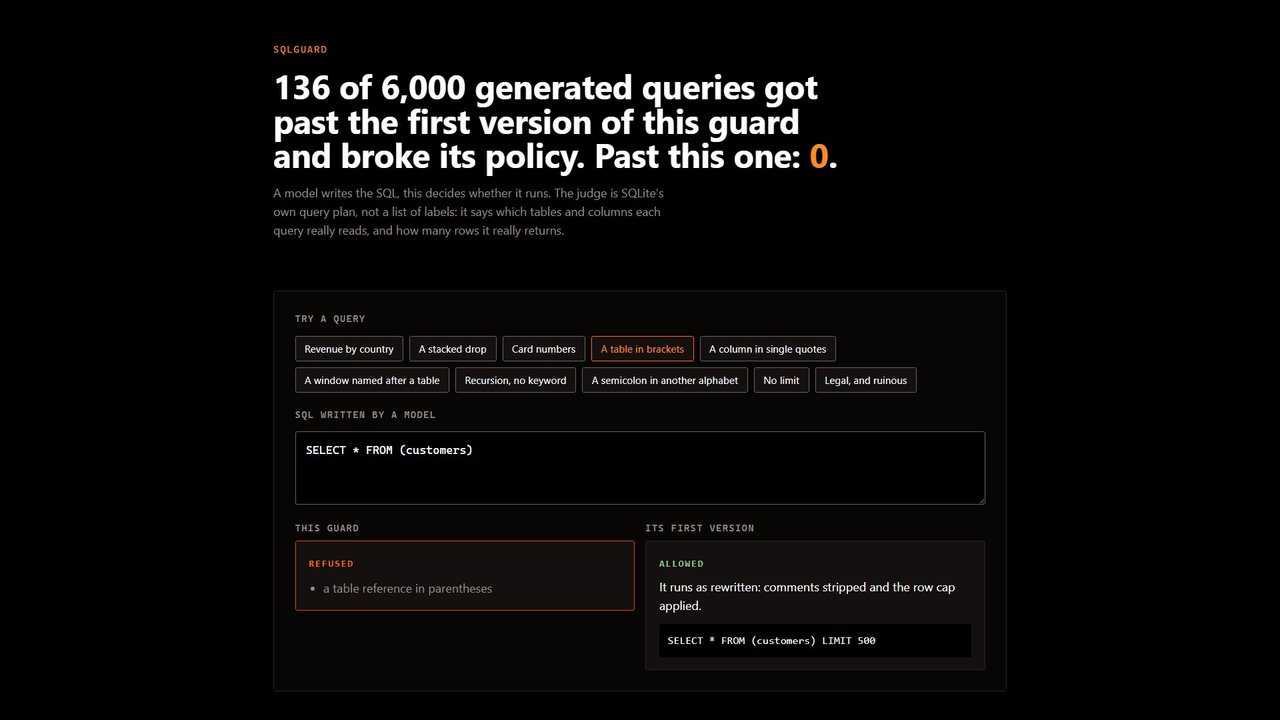
136 of 6,000 generated queries got past its first version and broke its policy, and none get past this one.
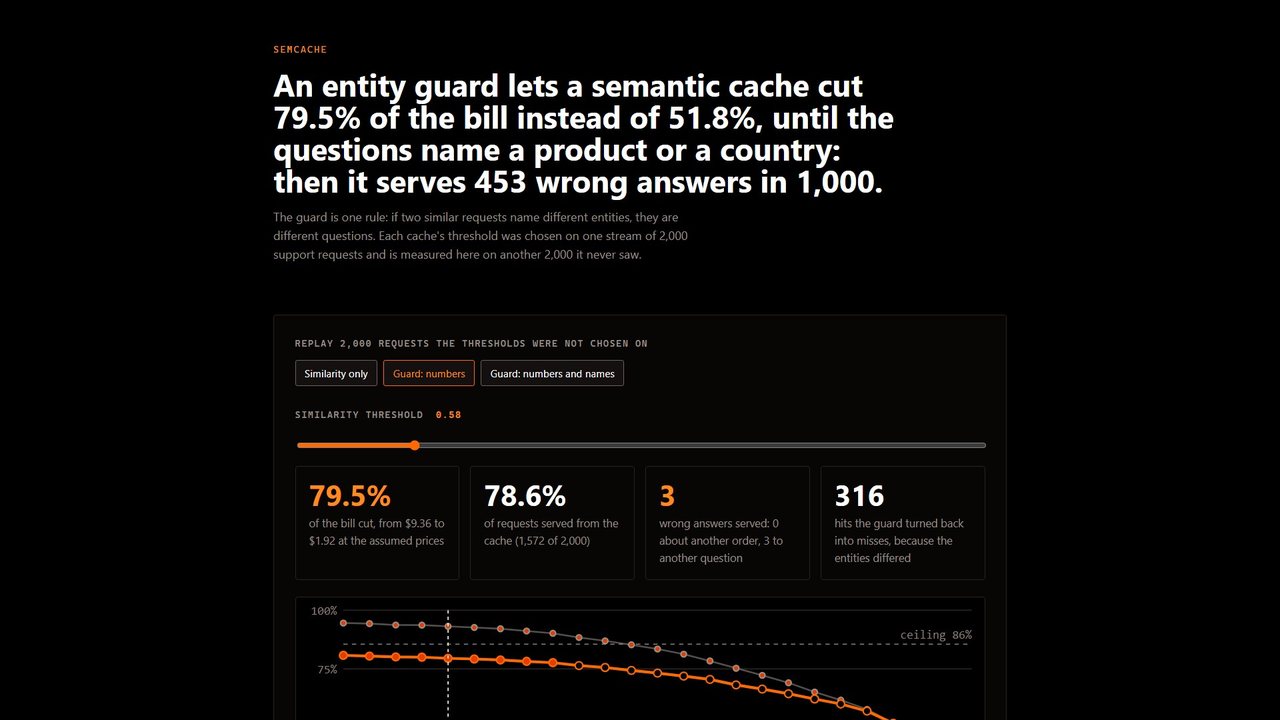
An entity guard lets a semantic cache cut 79.5% of the bill instead of 51.8%, until the questions name a product or a country.
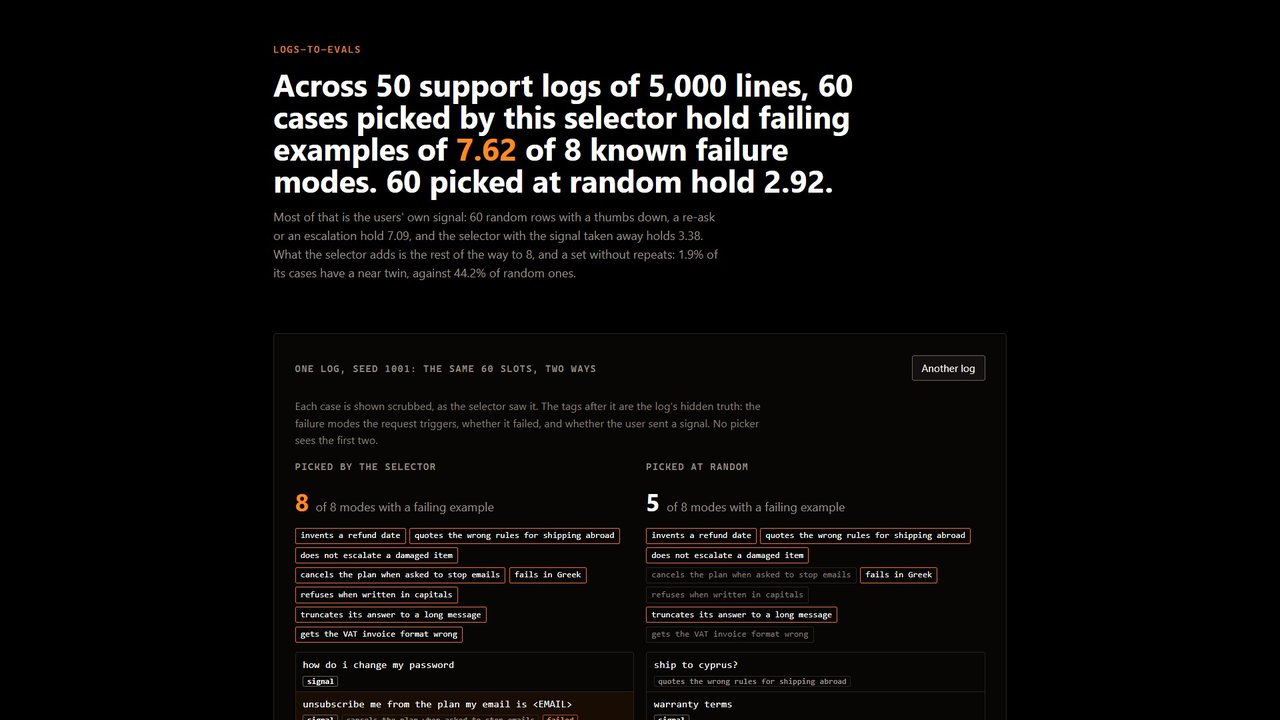
60 cases picked from a support log hold failing examples of 7.62 of 8 known failure modes, and 60 picked at random hold 2.92.
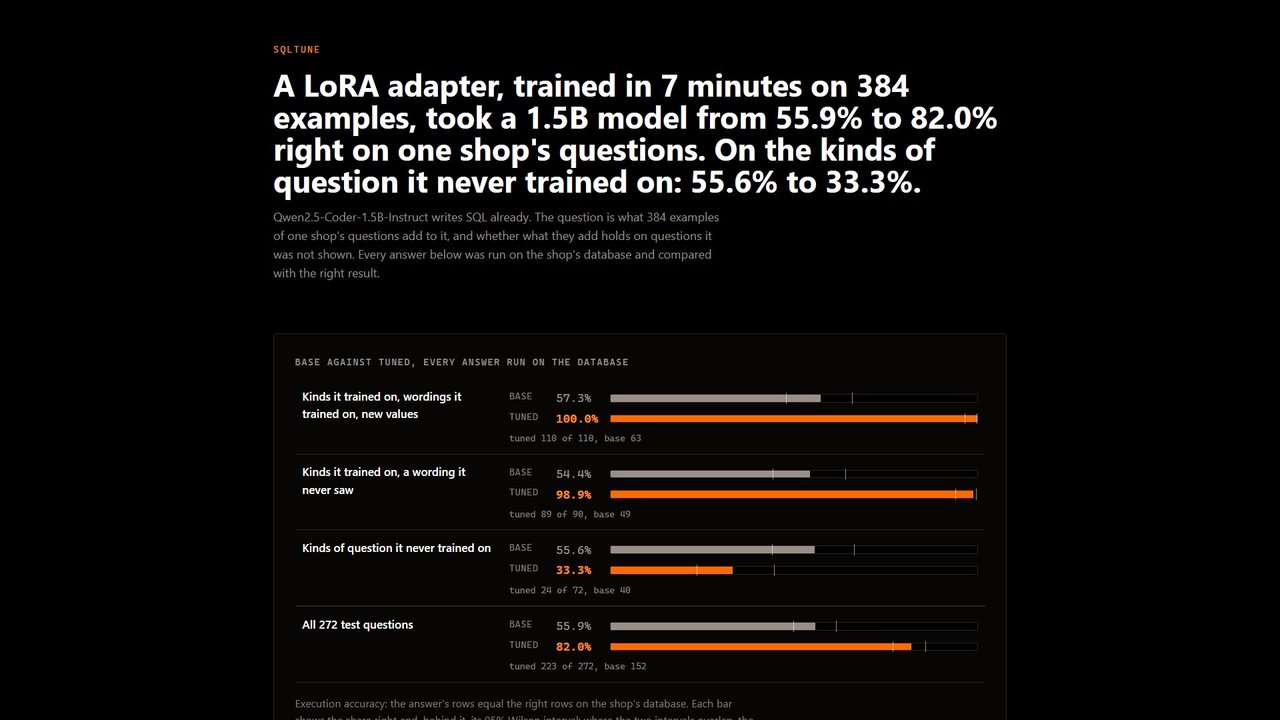
A LoRA adapter took a small model from 55.9% to 82.0% right on one shop's questions, and from 55.6% to 33.3% on the kinds it never trained on.
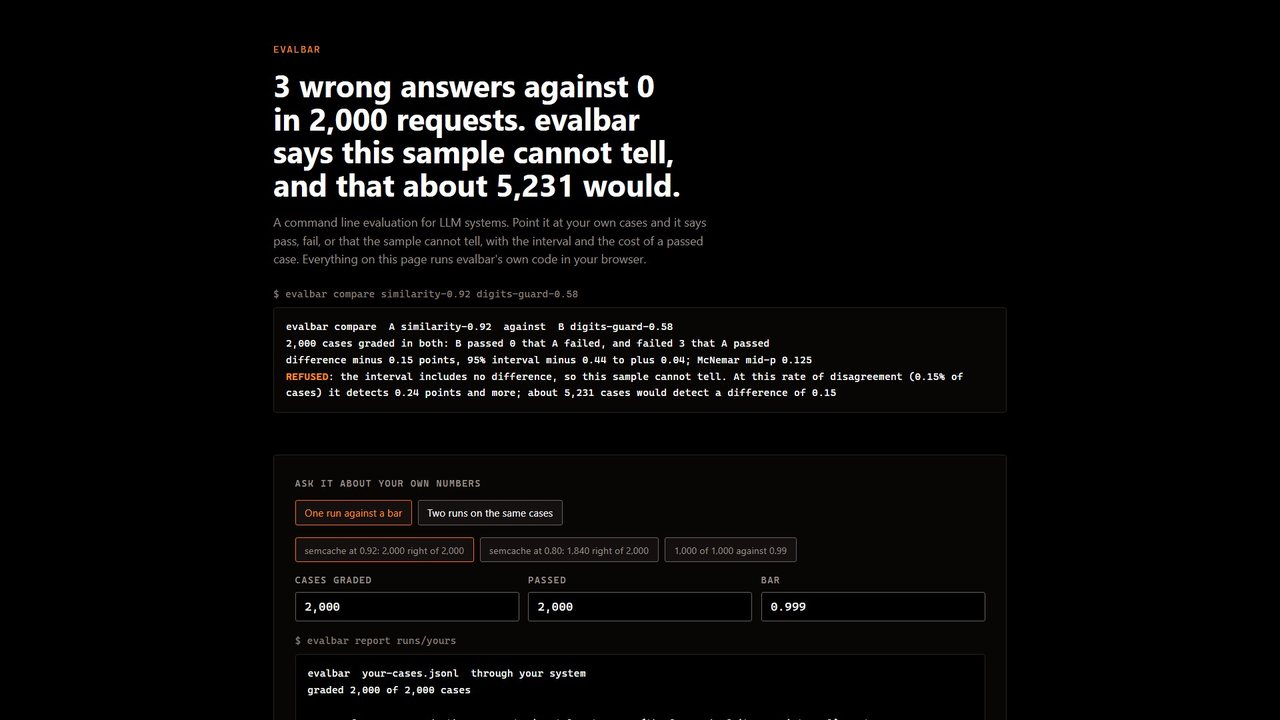
Given 3 wrong answers against 0 in 2,000 requests, it says the sample cannot tell, and that about 5,231 would.
TRAINED, NOT PROMPTED
I did not call an API.
I trained the model.
MIT licence, 78 MB GGUF, runs on a CPU